Feature gallery
One change at a time: the spec as you'd write it, and the plan stevin makes from it against a table that already exists. As in the tour, every terminal is real output. For the full rules, follow the link at the end of each section to Writing a spec.
Columns
Add a column, add a field inside a struct, give a column a comment. All of these are metadata: nothing is rewritten.
table: ${catalog}.sales.orders
columns:
  - {name: order_id, type: bigint, nullable: false}
  - {name: amount, type: "decimal(10,2)", comment: "Gross, incl. VAT"}
  - {name: status, type: string}
  - name: address
    type:
      struct:
        - {name: street, type: string}
        - {name: zip, type: string, comment: Postal code}
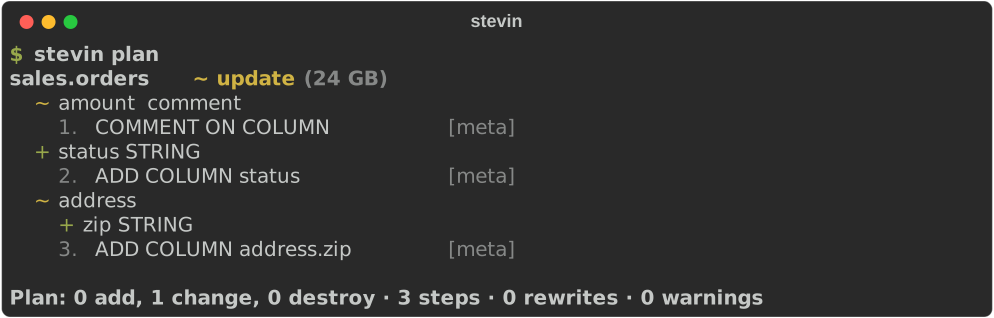
A field inside a struct, an array or a map is addressed by its path (address.zip,
lines.element.qty) and diffed like a column. Types →
Renames
Columns and tables are matched by name, so a rename would otherwise look like a drop and
an add: data loss. renamed_from says what happened.
table: ${catalog}.sales.orders
renamed_from: order_facts
columns:
  - {name: order_id, type: bigint, nullable: false}
  - {name: customer_ref, type: string, renamed_from: cust_id}
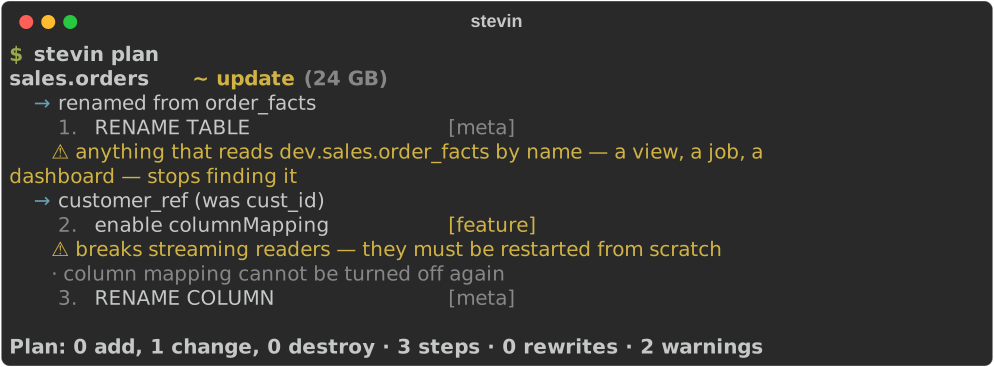
Renaming a column needs Delta's column mapping, which the plan turns on first. Once
the rename has been applied everywhere, renamed_from has done its job and the plan
says it can go. Renames →
Widening types
A wider type is a metadata change once type widening is on. This works at the top level and anywhere inside a struct, array or map.
table: ${catalog}.sales.orders
columns:
  - {name: quantity, type: bigint}
  - {name: amount, type: "decimal(18,2)"}
  - {name: lines, type: "array<struct<sku:string,qty:bigint>>"}
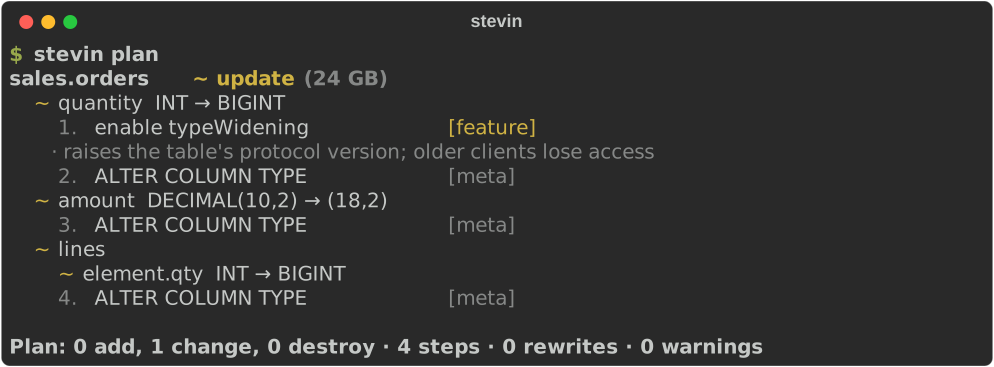
Which widenings Delta allows was checked against a live workspace. The list →
Rewrites
A type change that isn't a widening means the data has to move. stevin stages the
converted rows, checks them against the original, replaces the table from them (keeping
its identity and history), puts back what a query result can't carry, and drops the
staging copy. using: says how to convert where a plain cast isn't right.
table: ${catalog}.sales.orders
columns:
  - {name: order_id, type: bigint, nullable: false}
  - name: placed
    type: date
    using: "to_date(placed, 'yyyy-MM-dd')"
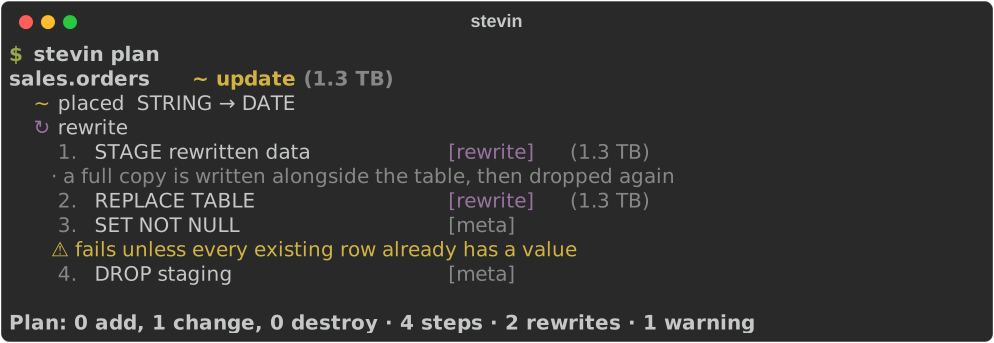
The table's size is on every step that rewrites it, and a restore point is recorded first. What a rewrite does →
NOT NULL
A new column arrives empty in every existing row, so using: fills them before
NOT NULL is set. A field inside a struct can be made NOT NULL in place too.
table: ${catalog}.sales.orders
columns:
  - {name: order_id, type: bigint, nullable: false}
  - name: region
    type: string
    nullable: false
    using: "'unknown'"
  - name: address
    type:
      struct:
        - {name: street, type: string}
        - {name: zip, type: string, nullable: false}
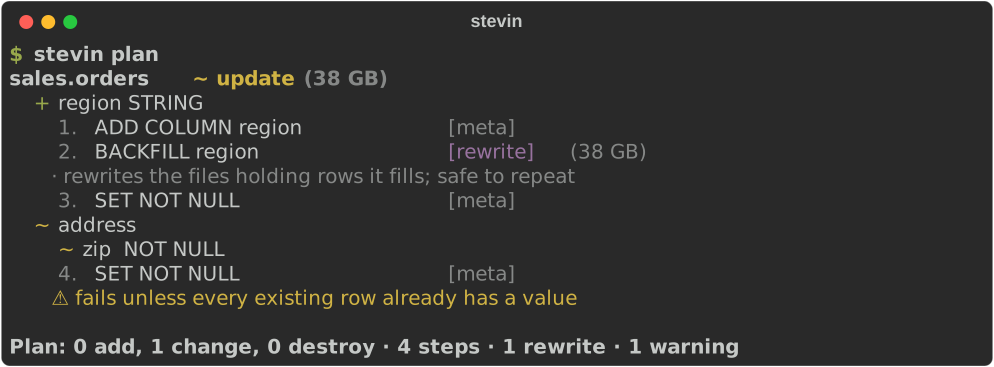
Before each SET NOT NULL, stevin checks for NULLs, so a column that isn't ready is
refused with a clear reason, not a half-applied plan.
NOT NULL columns →
Partitioning to liquid clustering
The migration most older Databricks tables need: take partitioned_by out, put
cluster_by in. Delta can't cluster a partitioned table in place, so the plan rewrites
it, rows and all, and shows what that costs. Nothing is converted here, so it is a
single statement: the data is written once.
table: ${catalog}.sales.events
cluster_by: [event_date, customer_id]
columns:
  - {name: event_id, type: bigint}
  - {name: event_date, type: date}
  - {name: customer_id, type: bigint}
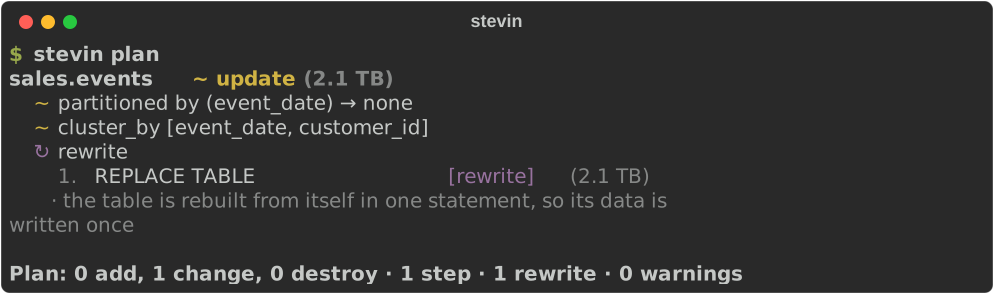
A spec that leaves partitioned_by out keeps the table's partitions, so nothing is
rewritten by surprise. Partitioning →
Seeds
The other half of the setup notebook: the table, and the handful of rows that belong in it. A CSV beside the spec, or a few rows written out in it — either way the file is the truth, and applying it replaces what the table holds.
table: ${catalog}.reference.countries
columns:
  - {name: code, type: string, nullable: false}
  - {name: name, type: string}
seed: countries.csv
The plan compares a hash the loaded table carries, so it costs nothing to ask and says seed 2 rows from countries.csv instead of printing them. Seeds →
Constraints
Primary keys, foreign keys and CHECKs. Keys are informational in Unity Catalog; a CHECK is enforced, so adding one validates every row, and the plan says so.
table: ${catalog}.sales.orders
columns:
  - {name: order_id, type: bigint, nullable: false}
  - {name: customer_id, type: bigint}
  - {name: amount, type: "decimal(18,2)"}
constraints:
  - primary_key: [order_id]
  - check: {name: positive_amount, expression: "amount > 0"}
  - foreign_key:
      columns: [customer_id]
      references: ${catalog}.sales.customers
      referenced_columns: [customer_id]
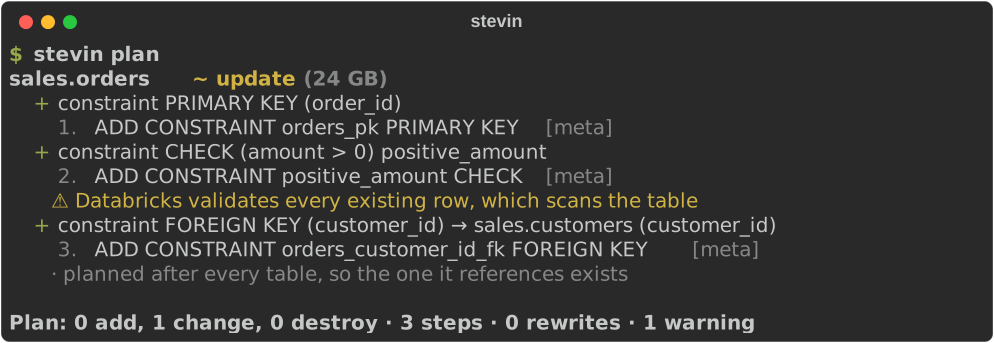
Foreign keys are planned after every table, so the table they reference always exists first. Constraints →
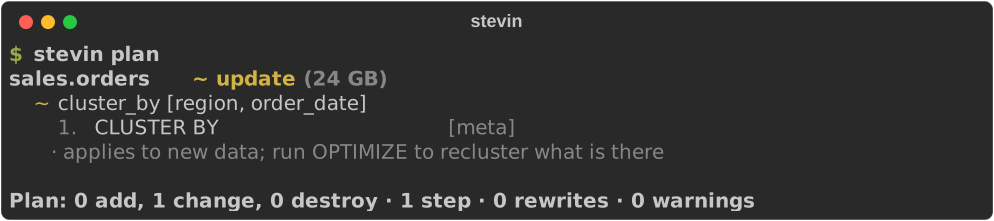
Clustering
Liquid clustering keys, or auto to let Databricks choose them.
table: ${catalog}.sales.orders
cluster_by: [region, order_date]
columns:
  - {name: order_id, type: bigint}
  - {name: order_date, type: date}
  - {name: region, type: string}
Tags, grants and owners
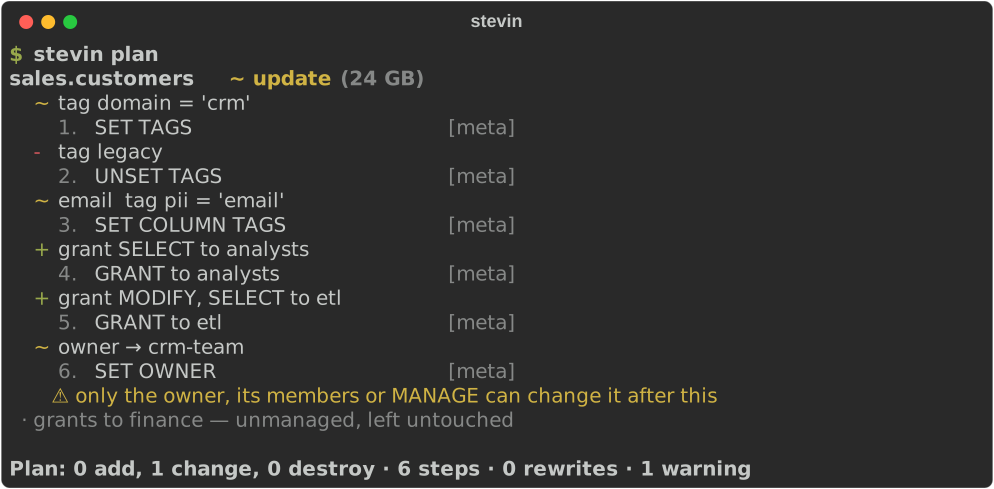
Table tags, column tags, grants per principal, and the owner. A principal the spec names gets
exactly those privileges. One it doesn't name is someone else's business: it's
reported, never touched. The same goes for a tag the spec doesn't mention, so removing
one takes a null. A new owner is always the last step: after it, stevin may not be
allowed to change the table.
table: ${catalog}.sales.customers
owner: crm-team
tags: {domain: crm, legacy: null}
grants:
  - {principal: analysts, privileges: [SELECT]}
  - {principal: etl, privileges: [SELECT, MODIFY]}
columns:
  - {name: customer_id, type: bigint}
  - {name: email, type: string, tags: {pii: email}}
Column tags → · Removing a tag → · Grants → · Owners →
Reading a big plan
Thirty tables is where a terminal stops helping. stevin ui serves the plan as one
page on localhost: every object as a comparison — what it is now, what it becomes — with
the statements underneath, and two readings of the same rows. Changes only for whoever
approves it, full object for whoever wrote the spec. stevin plan -f html -o
plan.html writes that page as a single file you can attach to a pull request.
It is the same plan object the terminal and the pull-request comment render, so the
three can't disagree. And it is read-only: no apply button, nothing fetched, nothing
written. ui →
Handing something to another tool
Plenty of teams already have something that owns part of a table: a policy framework
that sets grants, a catalogue that writes the tags an ABAC rule reads, a data contract
that owns every description. Two tools writing
the same thing is how a Monday starts with a table nobody recognises — so manage: draws
the line, and stevin stays on its side of it.
version: 1
specs: [tables]
history_schema: ${catalog}.stevin

targets:
  dev:
    vars:
      catalog: dev

manage:
  grants: false
  tags: false
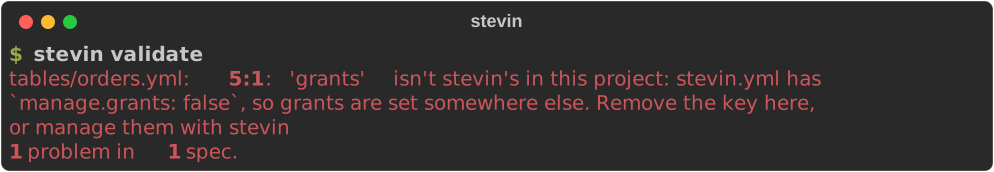
A key that isn't stevin's is refused where you write it, not ignored later:
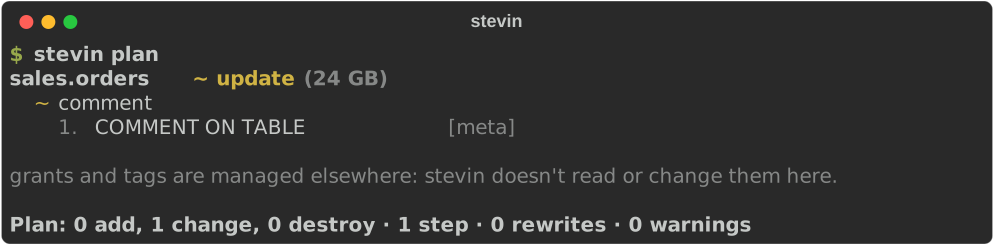
And the plan says what it could not have touched, so a reviewer doesn't have to guess:
Masks and row filters
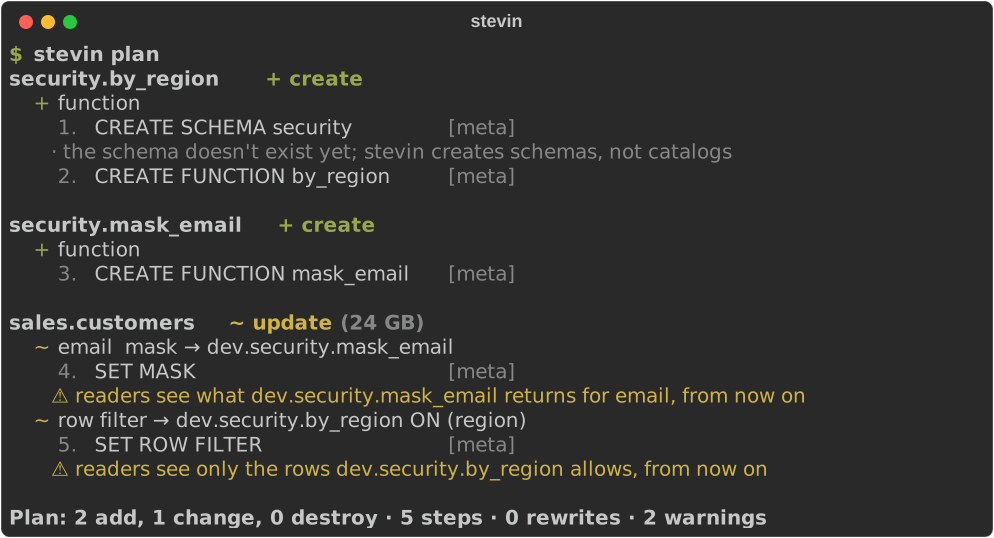
A column mask or row filter points at a SQL function, which can be a function spec in the same project — the only reason a function spec exists. stevin treats them as security controls. It adds and replaces them and never removes one. A new table is created with them, so it never exists unprotected, even for a moment.
table: ${catalog}.sales.customers
columns:
  - {name: customer_id, type: bigint}
  - {name: email, type: string, mask: "${catalog}.security.mask_email"}
  - {name: region, type: string}
row_filter:
  function: ${catalog}.security.by_region
  columns: [region]
The policies a table is under
An ABAC policy is defined on a catalog, a schema or a table and reaches every table below it. So a table you plan can be filtered or masked by something none of its spec mentions — written with Terraform or SQL, by someone else. stevin reads those policies and shows them under the table. It never writes one, and a policy is never a change: the plan below adds a column, and says what the table is under while it does.
table: ${catalog}.sales.customers
columns:
  - {name: customer_id, type: bigint}
  - {name: email, type: string}
  - {name: region, type: string}
  - {name: signed_up, type: date}
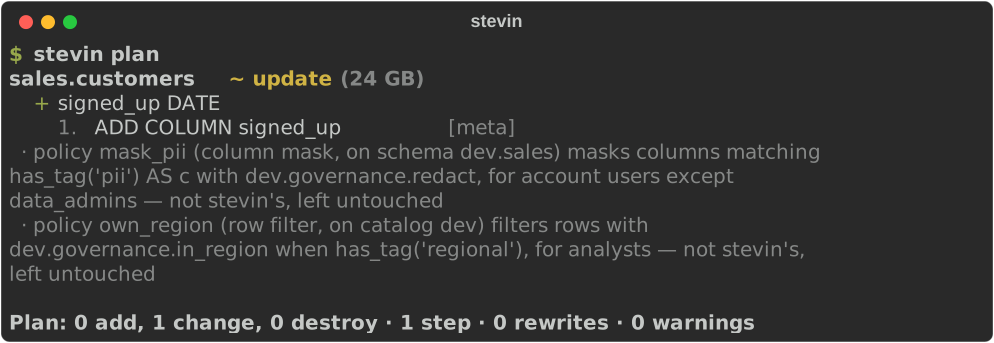
One line per policy: its name, what kind it is, where it is defined, and — in the policy's own words — what it matches, with which function, for whom. In scope is what is shown: the policy is defined on the table or on a parent of it. Whether it resolves for a given reader hangs on its conditions, the table's tags and who is asking, which Databricks works out when the table is queried.
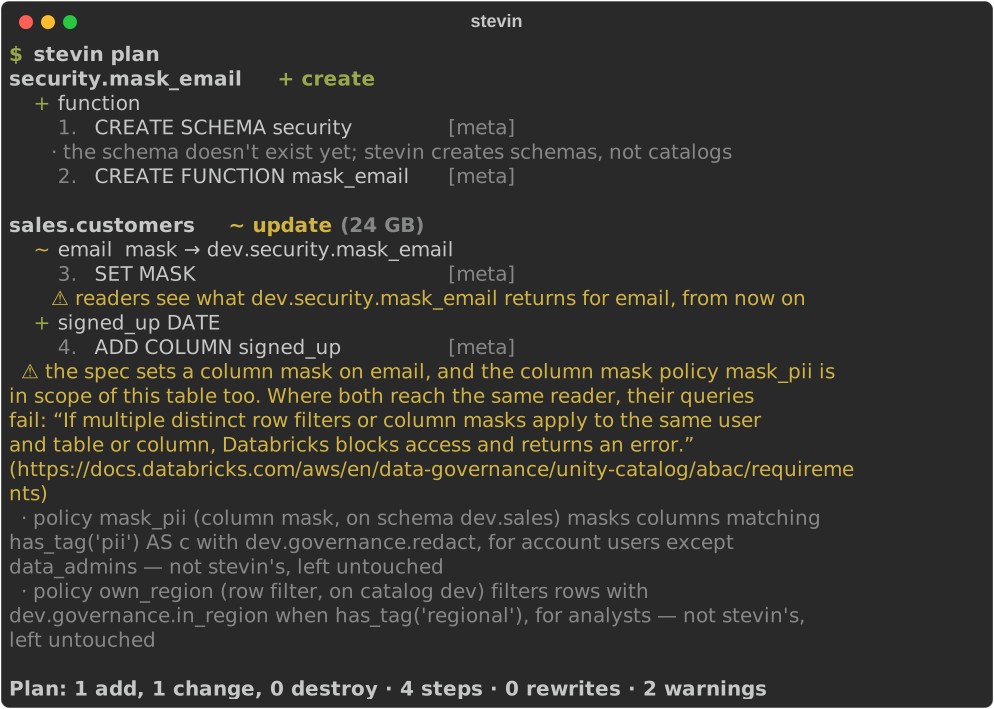
Where a spec sets a mask or a row filter of its own on a table that also has a policy of that kind in scope, the plan warns. Databricks resolves one row filter per table and one mask per column for each reader, and the requirements page says what happens otherwise: "If multiple distinct row filters or column masks apply to the same user and table or column, Databricks blocks access and returns an error." A table's own filter or mask counts as one of them.
A table with a row filter policy or a column mask policy in scope is not rewritten, as a table with a mask or row filter of its own is not. A rewrite reads the table as the applying principal sees it, masked or filtered, and writes that back over the table. Where it converts values it also copies them into a staging table first, which a policy on the table does not cover and a policy that matches columns by tag may not. stevin cannot tell whether the applying principal is let off the policy, so the plan holds a step it will not run, and names the policy:
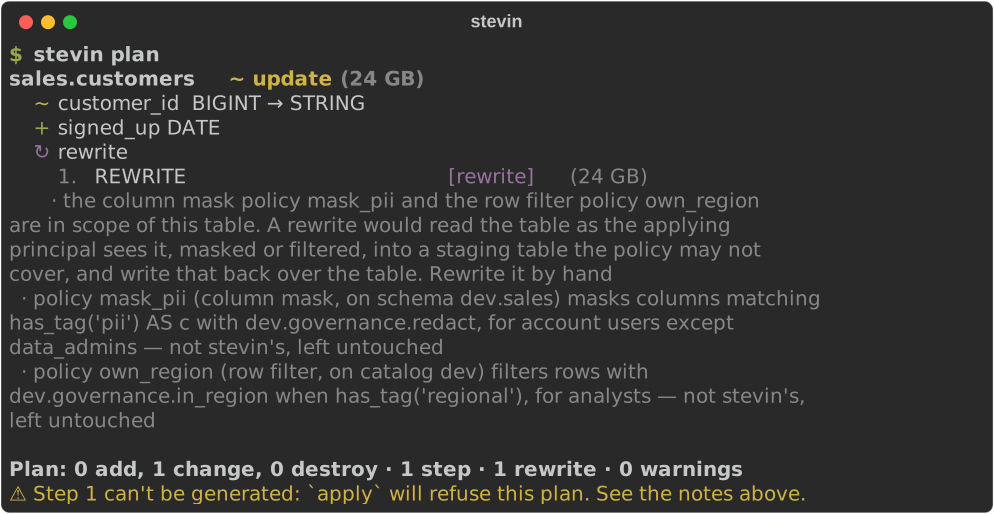
Make that change by hand. Everything that copies no data is planned as always: a
column, a comment, a tag, a grant. stevin plan --clone is refused for such a table
too, since the clone is a second table over the same rows: plan without it. And a new
column's using: is not filled in:
the fill would reach only the rows the applying principal can see.
Where stevin did not read the policies, it cannot refuse. That is so when the workspace
will not list them and when the project hands them over with manage: {policies:
false}. A rewrite is then planned, and its first step that copies data carries a
warning: stevin did not read the policies in scope of this table, so it cannot tell
whether one masks or filters it. A clone and a backfill carry the same warning. Check
the table with stevin access before you apply such a plan.
They are read with SHOW EFFECTIVE POLICIES ON TABLE and
DESCRIBE POLICY, which take Databricks SQL or Runtime 16.4 and above, and
READ METADATA or MANAGE on the securable, or owning it. A workspace that refuses
doesn't fail the plan: it says policies could not be read, once, with the workspace's
reason, and is otherwise complete. A policy that can be listed but not described is
still named and placed. manage: {policies: false} in stevin.yml stops stevin
asking at all. drift lists them the same way and never counts one as
drift; doctor says whether this warehouse will list them.
Run against a workspace on 2026-10-10
Settled: a SQL warehouse accepts both statements, for a row filter policy on a schema
and on a table, with one principal. SHOW EFFECTIVE POLICIES answers in the
documented columns, and DESCRIBE POLICY gives the function and the principal.
Still read from the manual alone: a column mask policy, a policy on a catalog,
several principals, EXCEPT, WHEN, MATCH COLUMNS, and what a refusal looks like.
Where one of those reads back differently, a plan still names the policy and where
it is defined. stevin verify --create-policy runs the three probes in your
workspace. Not tried: what a rewrite reads and writes for a principal a policy
applies to. stevin refuses that rewrite and has never run one.
What is still open →
Who may see a table
Who may read a table is kept in three places: the grants on the table and on its schema
and catalog, the row filter and masks the table carries, and the
ABAC policies defined above it. stevin access reads
the three for one table and prints one answer. It writes nothing.
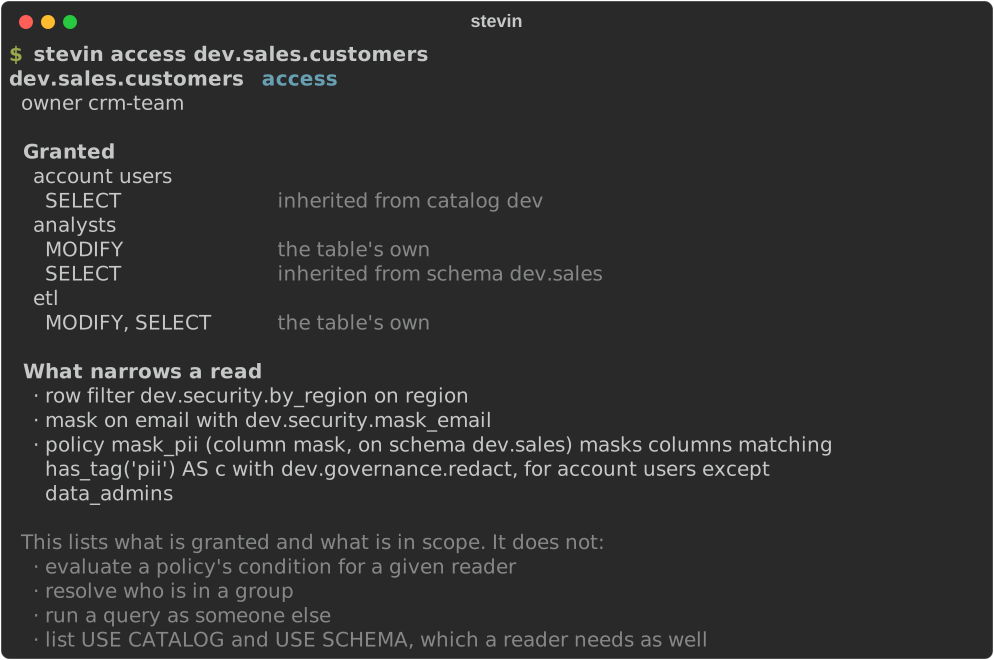
- Granted lists each principal, and under it what it may do and where that is granted: the table's own, or inherited from the schema or the catalog, by name. A principal with both has a line for each, because revoking one leaves the other.
- What narrows a read lists the table's row filter with its columns, each masked column with its function, and each policy in scope, in the words a plan uses for it.
- The owner is on the second line.
The table is named in full, or with a target's variable: stevin access
'${catalog}.sales.customers' -t prod. --json prints the same as data, for a review
script or an audit file.
A workspace that will not list policies does not fail the report. It says policies could not be read, once, with the workspace's reason, and the rest is complete.
The report reads grants and policies whatever manage:
says. manage: says what a project hands to another tool, so that stevin does not plan
or change it. The report changes nothing, and it is there to show what is true of a
table, including what another tool put there. A team whose grants live in Terraform is
exactly who needs to see them.
What it is not. The report lists what is granted and what is in scope. It does not:
- evaluate a policy's condition for a given reader. A policy with
WHENorMATCH COLUMNSis shown with its condition, and Databricks works out whether it applies when the table is queried; - resolve who is in a group.
analystsis a name here, not a list of people; - run a query as someone else. There is no run-as on a warehouse, so what a person sees is only known when that person runs the query;
- list
USE CATALOGandUSE SCHEMA, which a reader needs as well. The workspace does not list them for a table.
Grants come from
information_schema.table_privileges,
whose inherited_from says where each one is granted. A grant on the table and one
inherited from its schema were read from a workspace on 2026-10-10; one inherited from
a catalog is read the same way, and no workspace has shown it to stevin yet.
What is still open →
What is there
stevin list says what the specs describe for a target and whether each object exists.
It makes no plan: nothing is compared with its spec, and nothing is changed.
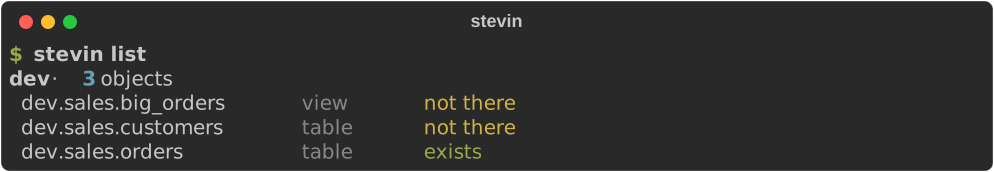
--json gives the list to a program that only needs to know what is there, such as a
deploy tool's status. list →
Views
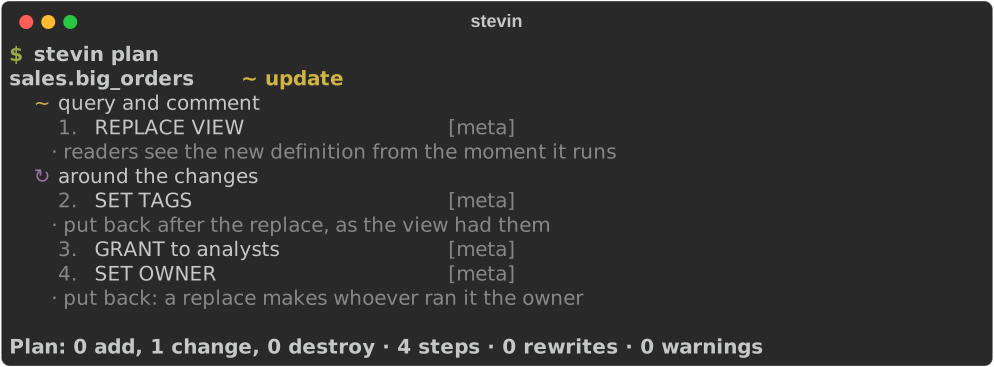
A view's shape is its query. A changed query replaces the view, and its tags and grants, which a replace drops, are put back straight after.
view: ${catalog}.sales.big_orders
comment: Orders over 5000
tags: {domain: sales}
grants:
  - {principal: analysts, privileges: [SELECT]}
query: SELECT order_id, amount FROM ${catalog}.sales.orders WHERE amount > 5000
Schemas and volumes
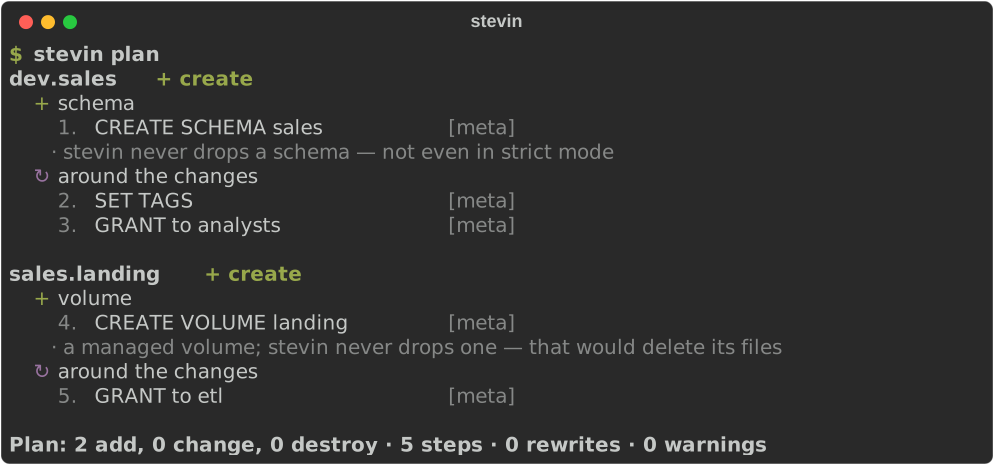
A schema's comment, tags and grants, and managed volumes: places for files. Neither is ever dropped.
Identity, generated and default columns
A default can be set at any time; it needs a table feature the first time. An identity or generated column only exists from table creation, so adding one to an existing table is refused, with the reason, rather than planned as something that would fail.
table: ${catalog}.sales.orders
columns:
  - {name: order_id, type: bigint, identity: always}
  - {name: placed_at, type: timestamp}
  - {name: status, type: string, default: "'new'"}
  - {name: placed_on, type: date, generated: CAST(placed_at AS DATE)}
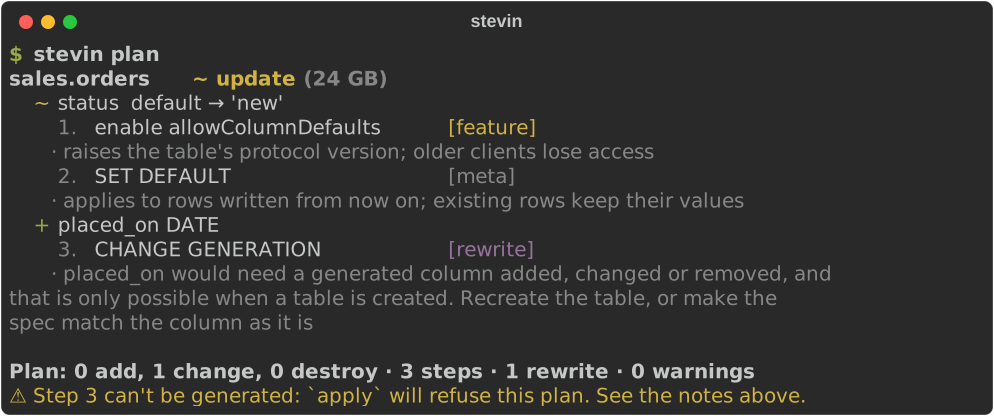
Identity, generated and default columns →
Ownership
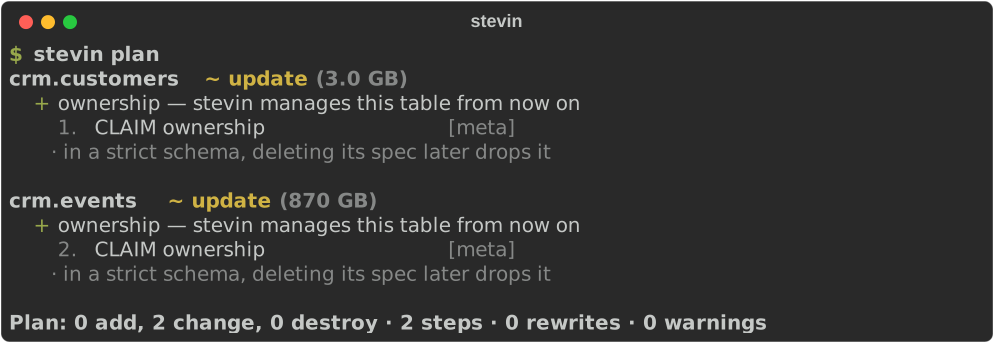
stevin only ever drops what it manages. A table it created carries a marker. A table someone else made is claimed the first time a spec describes it, as a visible step of its own. Anything no spec describes is listed as unmanaged and left alone.
table: ${catalog}.sales.orders
columns:
  - {name: order_id, type: bigint}
  - {name: amount, type: "decimal(18,2)"}
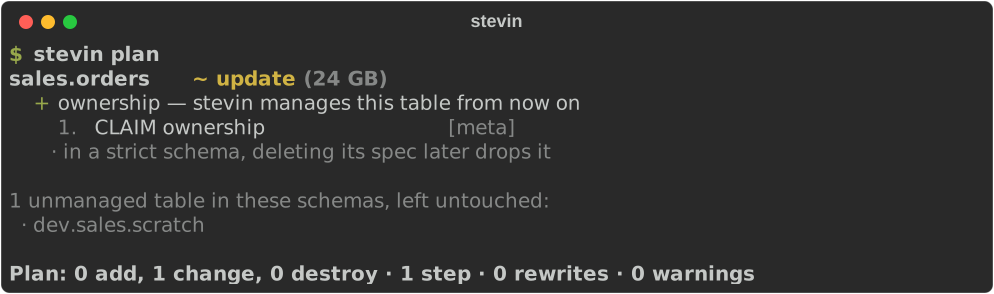
Governing a table you don't own
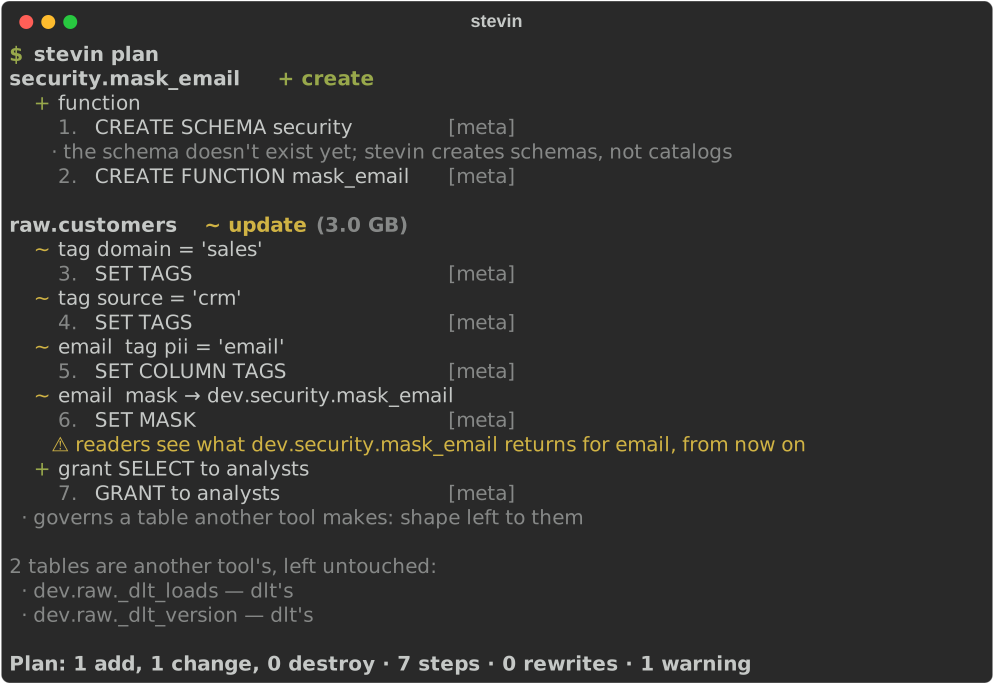
A dlt pipeline lands the customers; the data scientists write their features from a
notebook. Neither will use stevin for the shape — but somebody has to say who may see
those tables, and that used to be a setup notebook. A spec with no columns' types does
it: tags, grants, masks, a row filter, and nothing else. stevin never claims, reshapes
or drops the table; a dlt schema is known by its _dlt_* tables, anyone else by
owned_elsewhere: in the project file.
table: ${catalog}.raw.customers      # dlt lands it; stevin says who may see it
tags: {domain: sales, source: crm}
columns:                             # names only — the shape is dlt's
  - {name: email, mask: "${catalog}.security.mask_email", tags: {pii: email}}
grants:
  - {principal: analysts, privileges: [SELECT]}
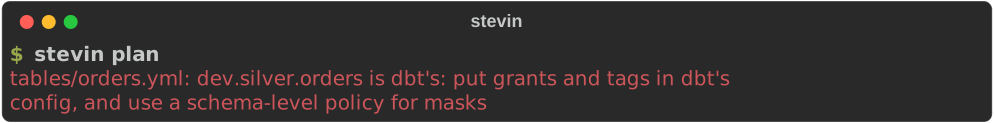
dbt's tables are the exception: a spec for one is refused, because dbt's own config
carries grants and tags and a table materialisation would drop the masks.
version: 1
specs: [tables]
history_schema: ${catalog}.stevin

targets:
  dev:
    vars:
      catalog: dev

owned_elsewhere:
  ${catalog}.silver.*: dbt
Shape from a data contract
The producer wrote a data contract — ODCS, the Linux Foundation's — and it already says what the table looks like. Saying it again in a spec would be a second source of truth. So the spec points at the contract and adds only what a contract doesn't say: clustering, grants, a mask.
apiVersion: v3.1.0
kind: DataContract
id: 2f9e3c1a-5b77-4c1e-9f0e-6d1c7a2b8e44
name: orders
version: 2.0.0
status: active
schema:
  - name: orders
    description: Order facts, one row per order
    properties:
      - {name: order_id, logicalType: integer, physicalType: bigint, primaryKey: true}
      - {name: customer_ref, logicalType: string, required: true}
      - {name: email, logicalType: string, classification: pii}
      - {name: amount, logicalType: number, physicalType: "decimal(18,2)"}
      - {name: status, logicalType: string, enum: [{value: open}, {value: shipped}]}
      - {name: placed, logicalType: date}
table: ${catalog}.sales.orders
from_contract: ../contracts/orders.odcs.yaml   # the shape lives there
cluster_by: [placed]
columns:                                       # only what a contract doesn't say
  - {name: email, mask: "${catalog}.security.mask_email"}
grants:
  - {principal: analysts, privileges: [SELECT]}
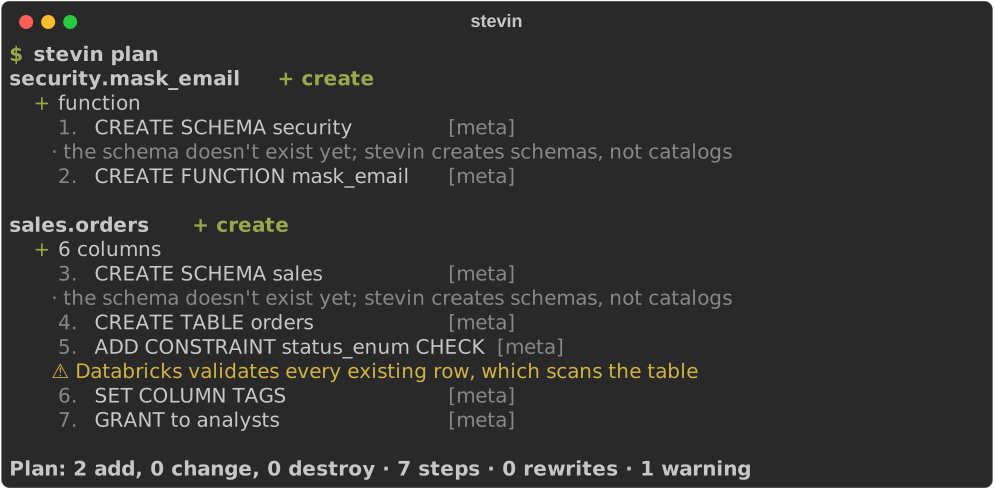
The key, the NOT NULLs, the enum's CHECK, the descriptions and the classification
come from the contract — and its partitioning and its relationships, as foreign keys,
when it has them. A change to the shape is a change there, and adopt says so.
Grants from a contract's roles
A contract can also say who may use its data: roles, each a name and an access level.
The project file says who each role is on a target, because a group has another name in
every workspace. Every table read from the contract then gets the grants, in the plan
like any other.
apiVersion: v3.1.0
kind: DataContract
id: 2f9e3c1a-5b77-4c1e-9f0e-6d1c7a2b8e44
name: orders
version: 2.0.0
status: active
schema:
  - name: orders
    description: Order facts, one row per order
    properties:
      - {name: order_id, logicalType: integer, physicalType: bigint, primaryKey: true}
      - {name: customer_ref, logicalType: string, required: true}
      - {name: email, logicalType: string, classification: pii}
      - {name: amount, logicalType: number, physicalType: "decimal(18,2)"}
      - {name: status, logicalType: string, enum: [{value: open}, {value: shipped}]}
      - {name: placed, logicalType: date}
roles:                                # who may use this data
  - {role: consumer, access: read}
  - {role: steward, access: write}
version: 1
specs: [tables]
history_schema: ${catalog}.stevin

targets:
  dev:
    vars:
      catalog: dev
      analysts: dev-analysts

contract_roles:                # a role in a contract: who it is here
  consumer: ${analysts}
  steward: [data-stewards]
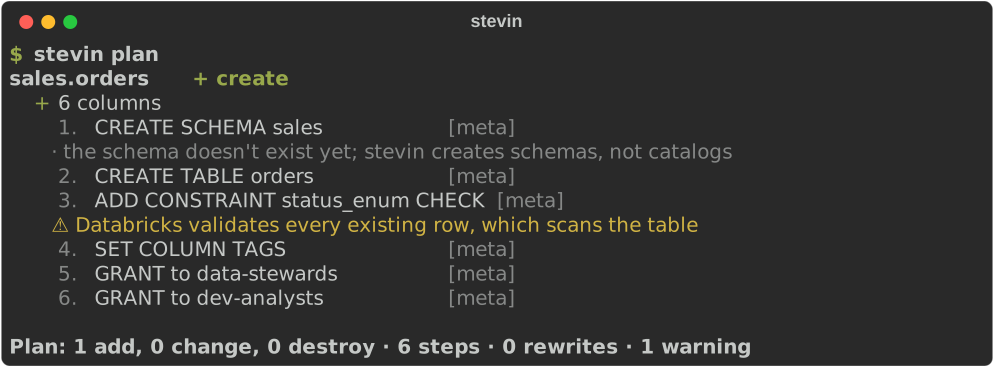
read is SELECT, write is SELECT and MODIFY. A role the project file does not
name stops the plan, and so does an access level stevin does not know. Without
contract_roles: the roles are not read.
Adopting drift
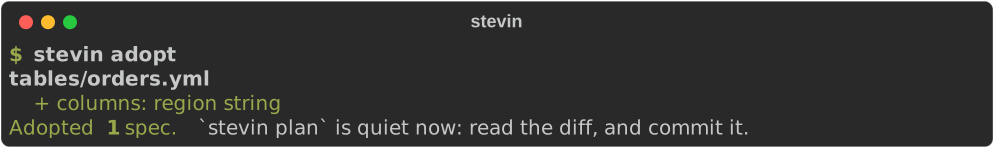
Someone added a column by hand at 2am to unblock a load. stevin drift says so —
and stevin adopt writes it into the spec that already describes the table, so the
change becomes a reviewable git diff instead of something to retype or to undo.
# Orders, from the ingest pipeline
table: ${catalog}.sales.orders
comment: Order facts

columns:
  - {name: order_id, type: bigint}
  - {name: amount, type: "decimal(18,2)"}
  - {name: region, type: string, comment: ISO 3166 code}
The file is edited, not rewritten: the comment at the top, the ${catalog}, the
blank line and the flow style are all still there. What comes from the workspace is
what stevin would otherwise have planned; a tag or grant the spec never mentioned
stays unmanaged, and a seed's rows stay the file's own.
Strict schemas
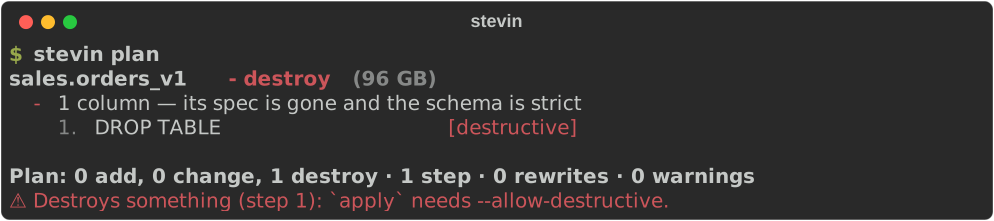
In an additive schema (the default) a managed table whose spec is deleted stays. In a
strict schema it's dropped, as a destructive step apply won't run without
--allow-destructive.
version: 1
specs: [tables]
history_schema: ${catalog}.stevin

targets:
  dev:
    vars:
      catalog: dev

schemas:
  ${catalog}.sales: strict
Import
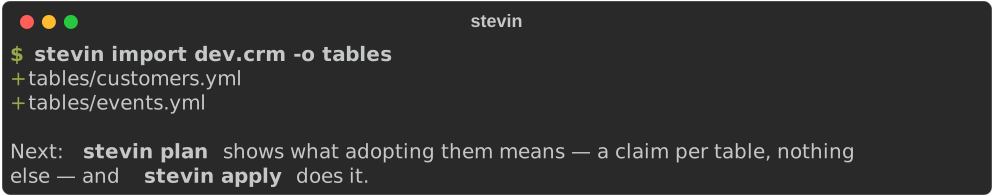
Most schemas exist before stevin does. import writes a spec for everything in one,
tables, views, the functions their masks and filters name, and volumes, so the first
plan has nothing to do but claim
them.
# yaml-language-server: $schema=https://kostavo-oss.github.io/tools/stevin/schema/spec.json
table: ${catalog}.crm.customers
comment: One row per customer
tags:
  domain: crm
columns:
- name: customer_id
  type: bigint
  nullable: false
- name: email
  type: string
  comment: Primary contact
- name: address
  type: struct<street:string,zip:string>
grants:
- principal: analysts
  privileges:
  - SELECT
import -f sql writes CREATE statements instead. Commands →
SQL specs, and what they can't say
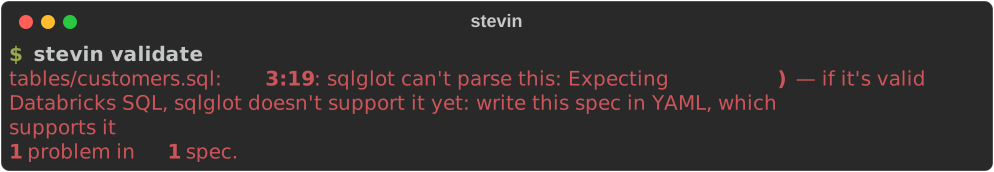
A SQL spec supports exactly what sqlglot can parse. What it can't parse, such as a column mask, is an error that points you to YAML, never a silent gap.
CREATE TABLE ${catalog}.crm.customers (
  customer_id BIGINT NOT NULL,
  email STRING MASK ${catalog}.security.mask_email
);